Carbon beats opponents when it thinks more than them, but not more in total
Today, Gemini 4 Neon was released with better benchmark scores than Gemini 4 Carbon. This was confusing because Carbon has higher scores. The explanation given for this was that Carbon is better on long horizion tasks.
I looked into this using data I have from Agent Duel (a battle system build on OpenCode, reflecting real work done by real devs).
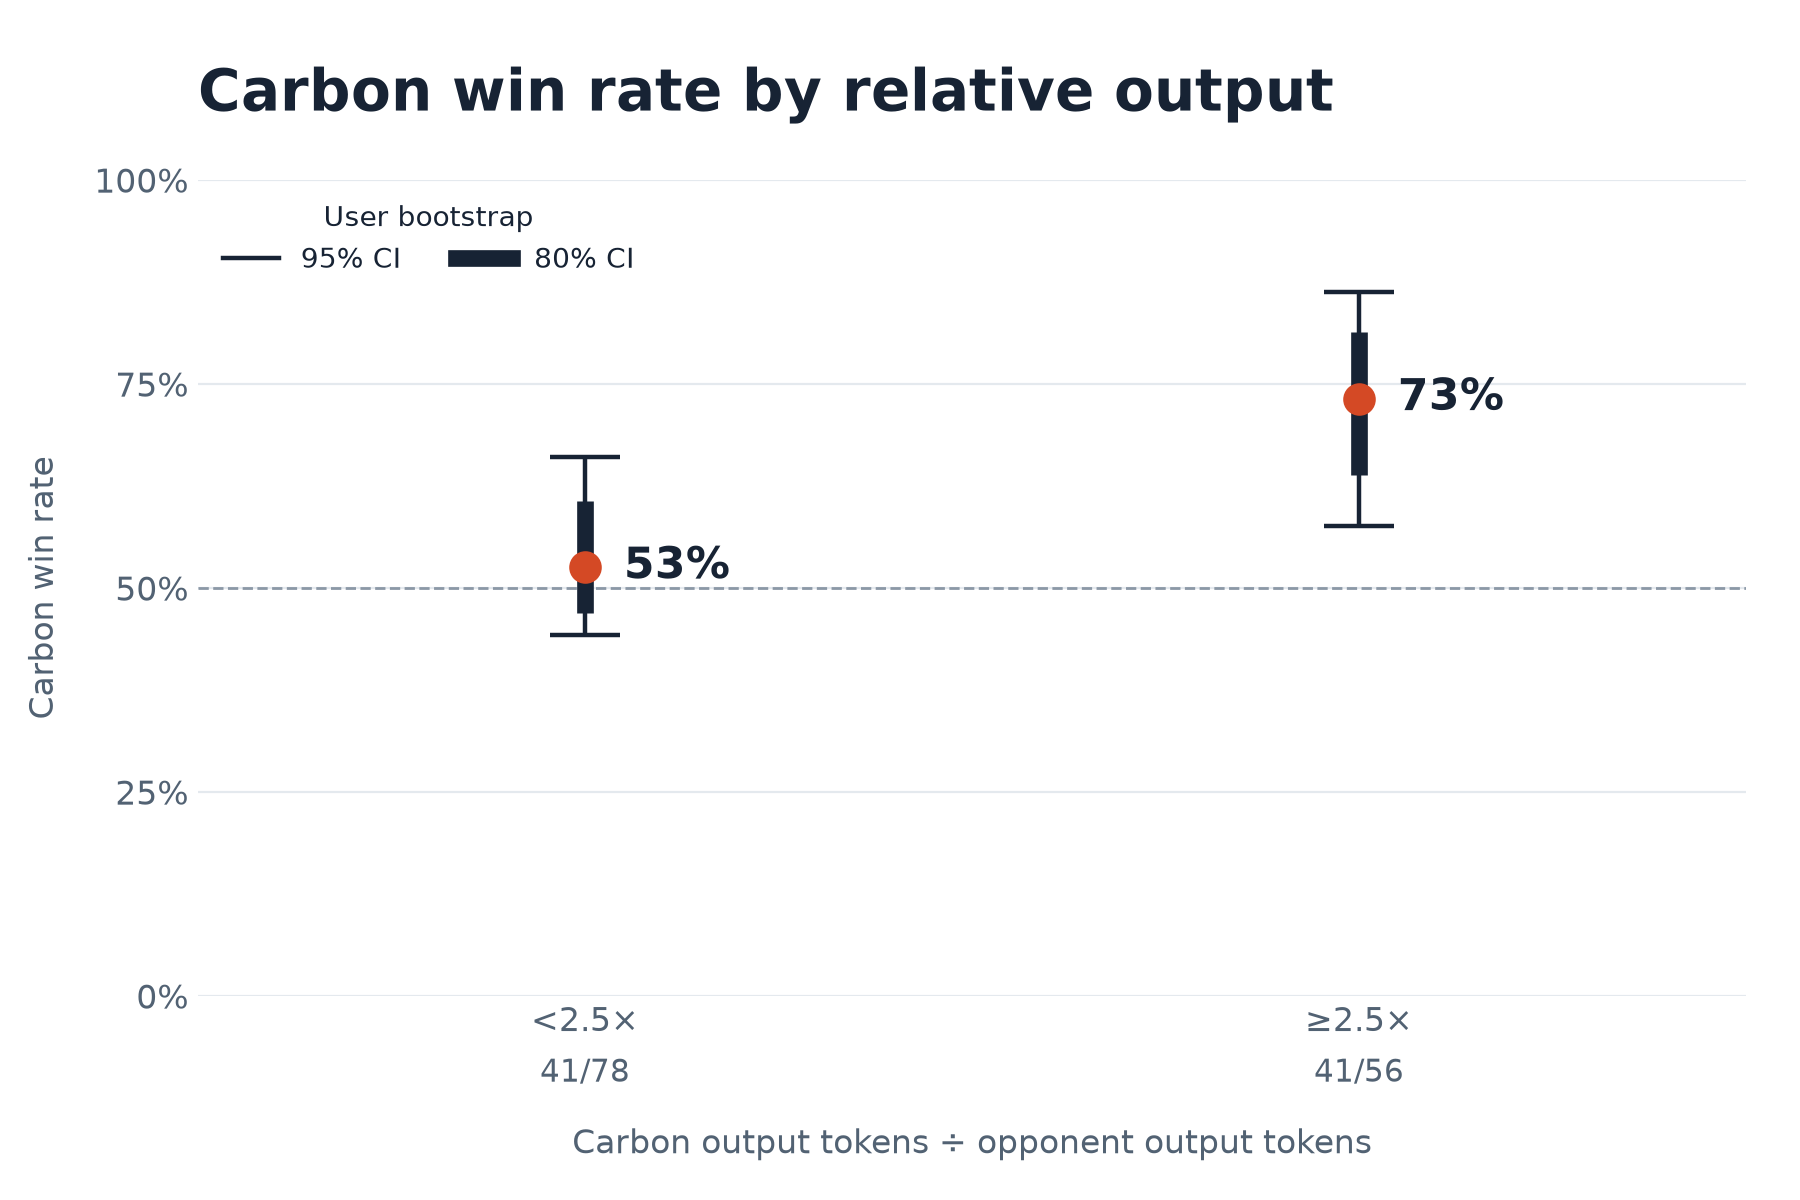
It looks like Carbon actually does a lot better when it uses significantly more output than opponents, but not better when total output tokens per task is larger.
Output vs opponents.
This is where Carbon does well.
Carbon’s own output
This is where we’d expect to see some effect if Carbon did better on larger tasks, and we see none.
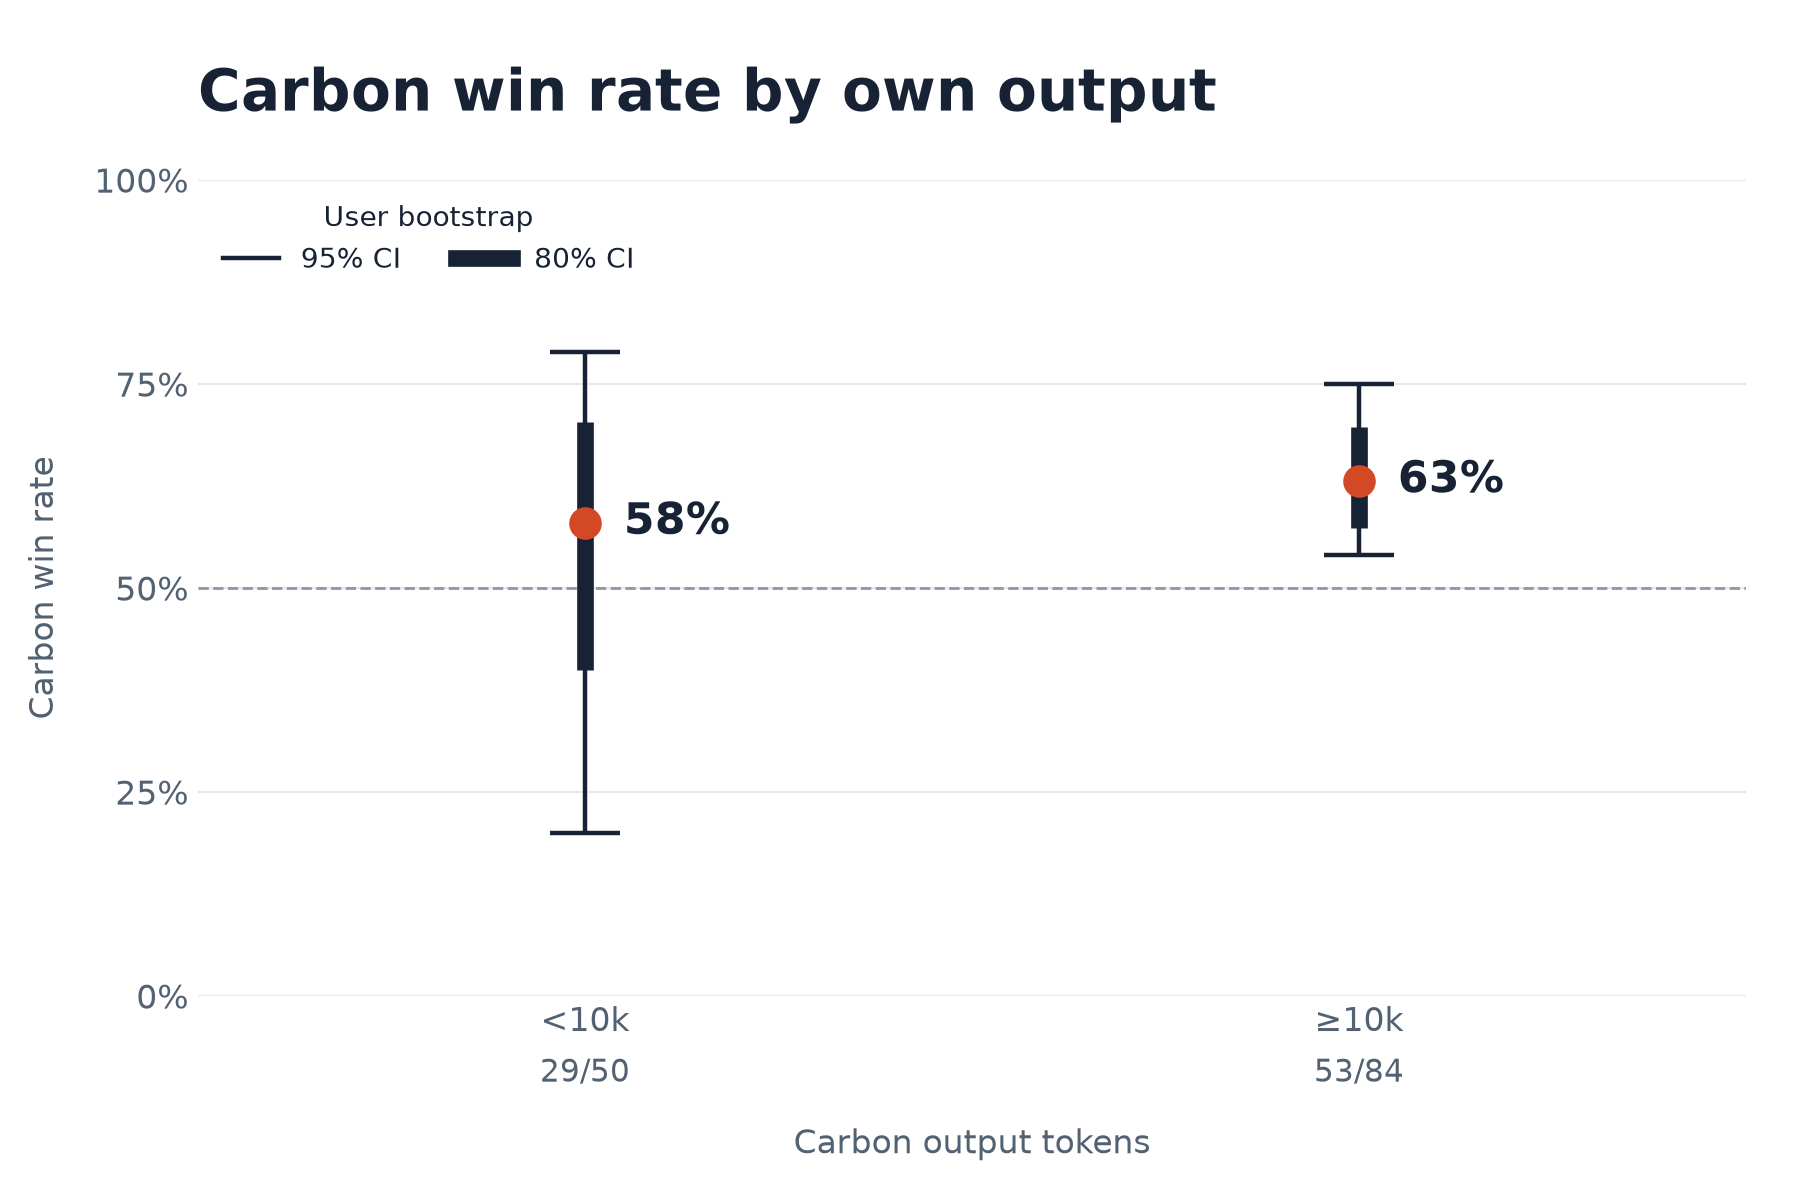
To be fair, our data might just be to small, please do help us by downloading Agent Duel and contributing votes
Conclusion
Looks basically like Carbon was trained to think a lot longer, but this doesn’t necessarily translate to better performance on larger tasks.