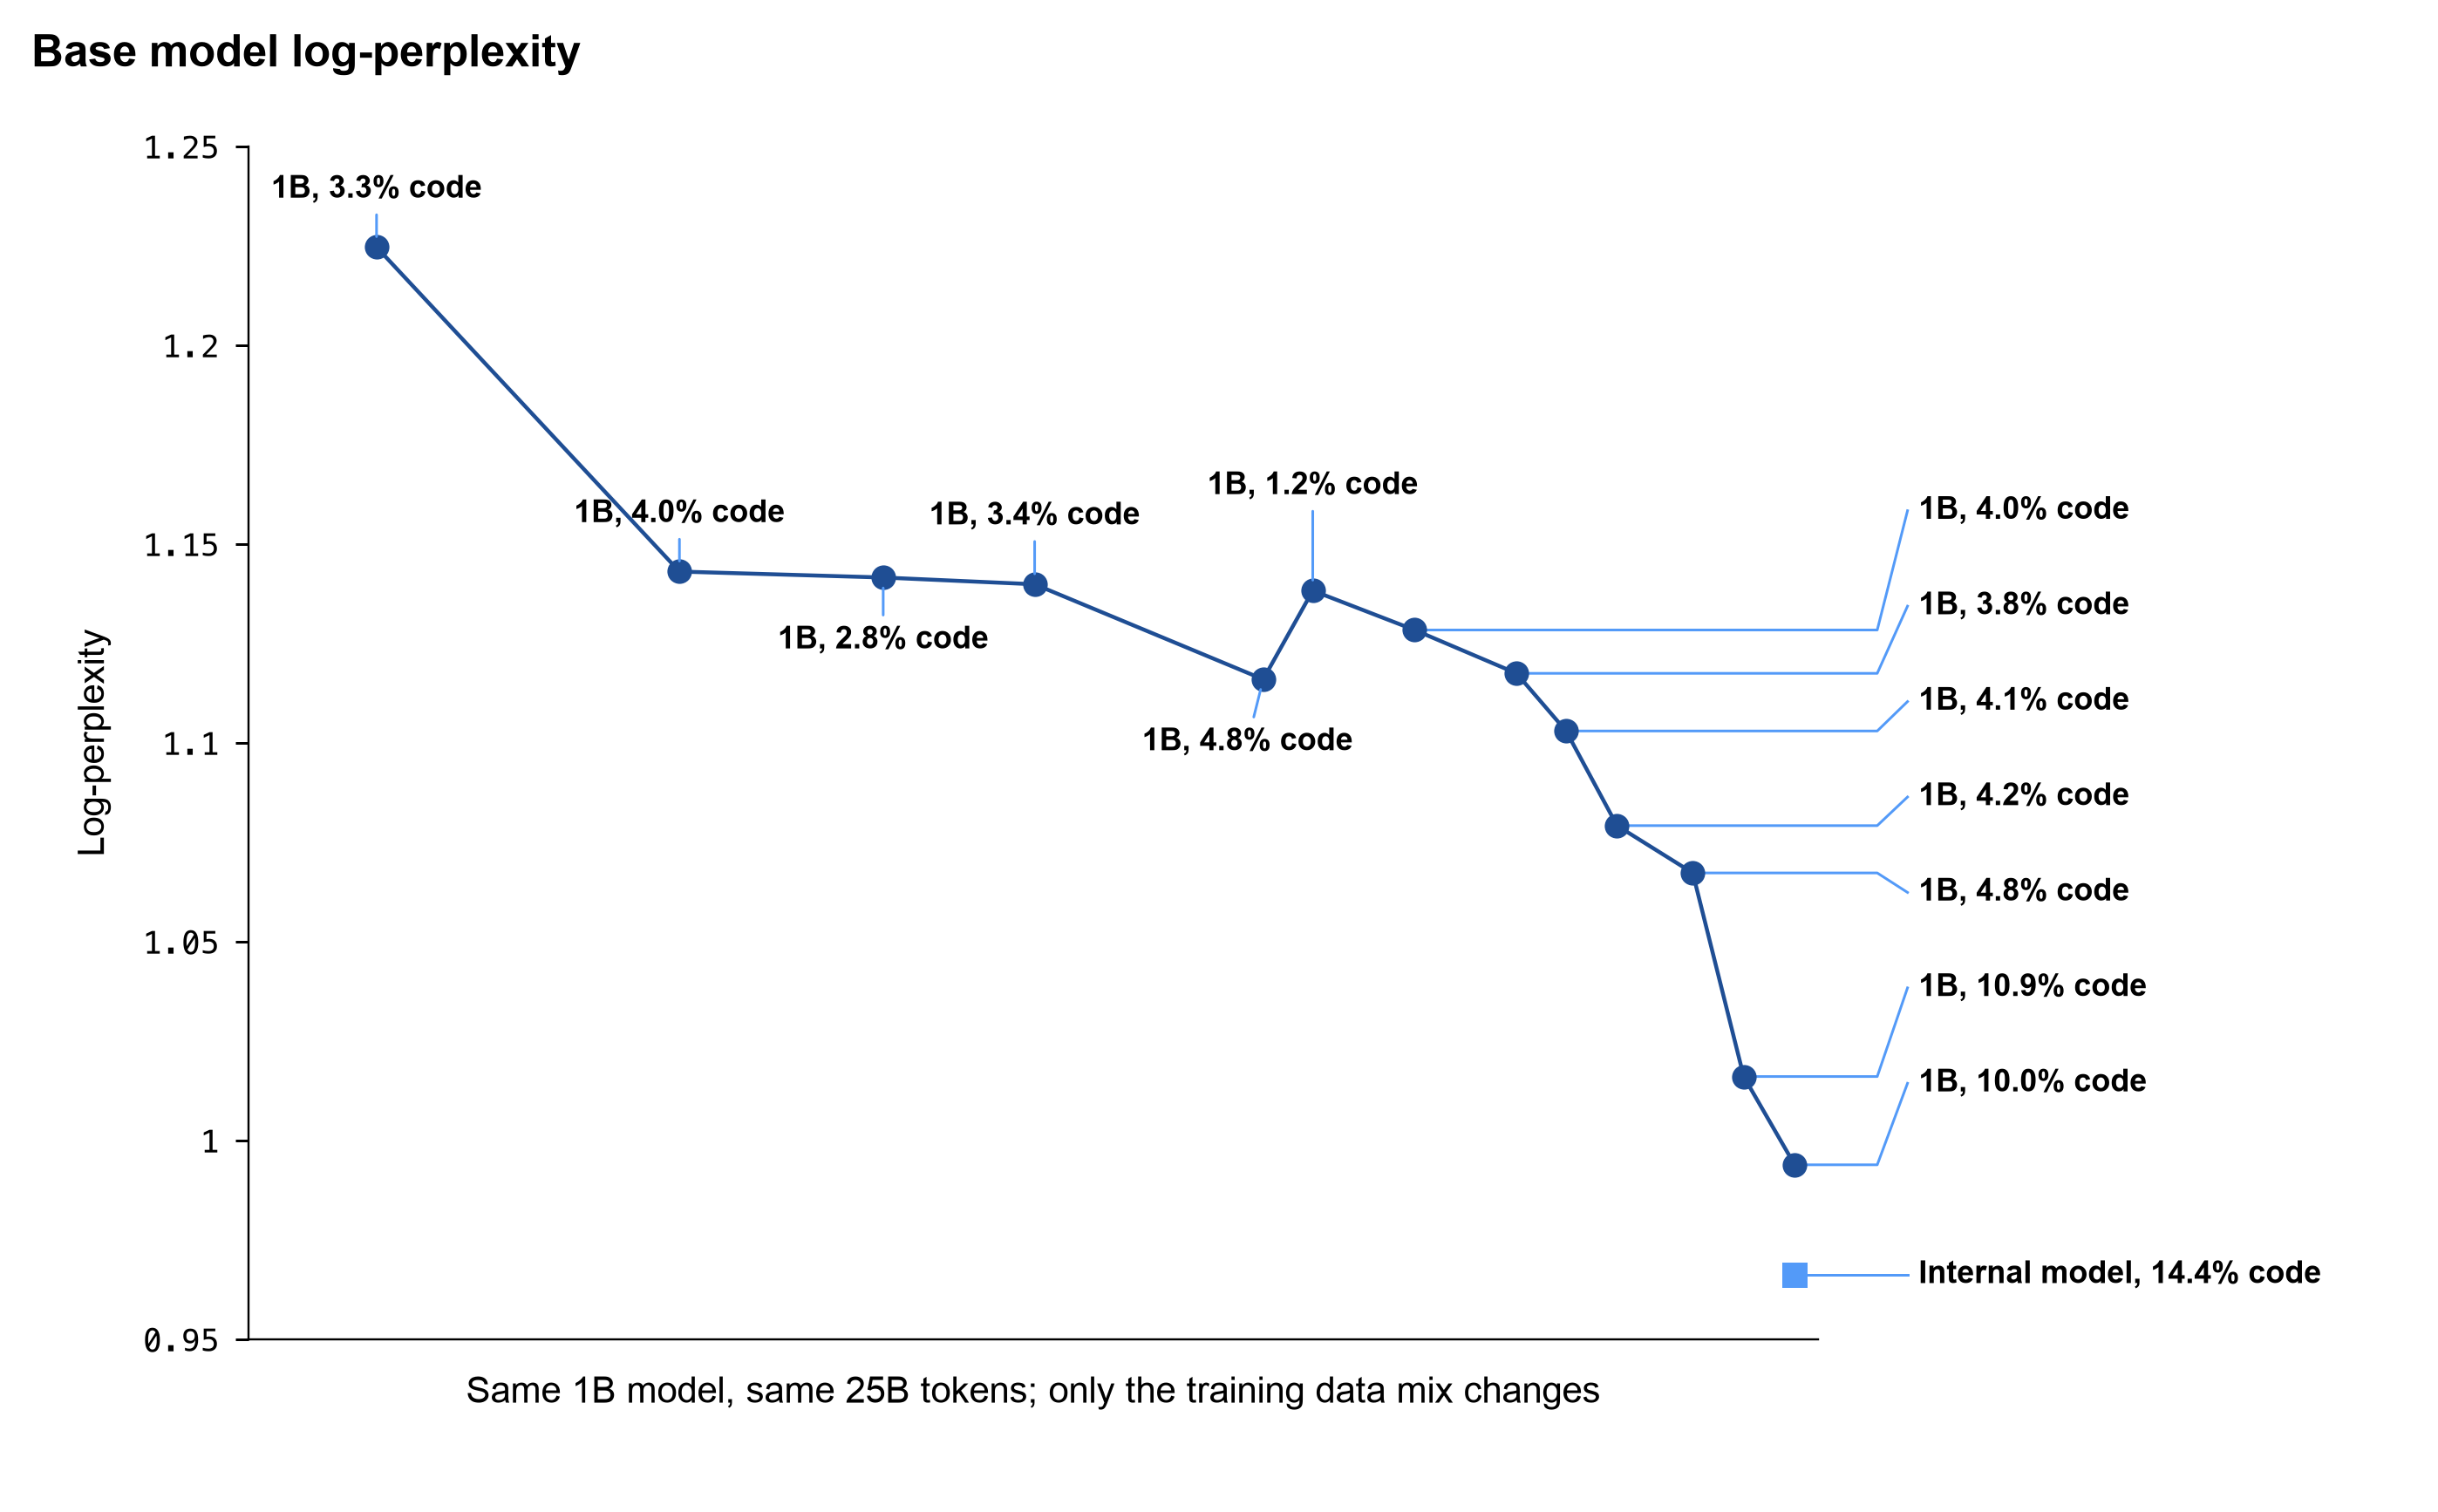
The exact same perplexity chart, from data mix alone
Earlier today, I published a blog post whose point was that OpenAI’s recent post showing pre-training progress was confounded by the percent of code in their pre-training corpus.
In the post, I demonstrated that if you vary the percent of code in your pre-training mix and you only evaluate log perplexity loss on a set of code, then you almost by definition get a reduction in log perplexity loss.
After publishing, I realized I could do one better and generate something in the shape of the exact same chart: